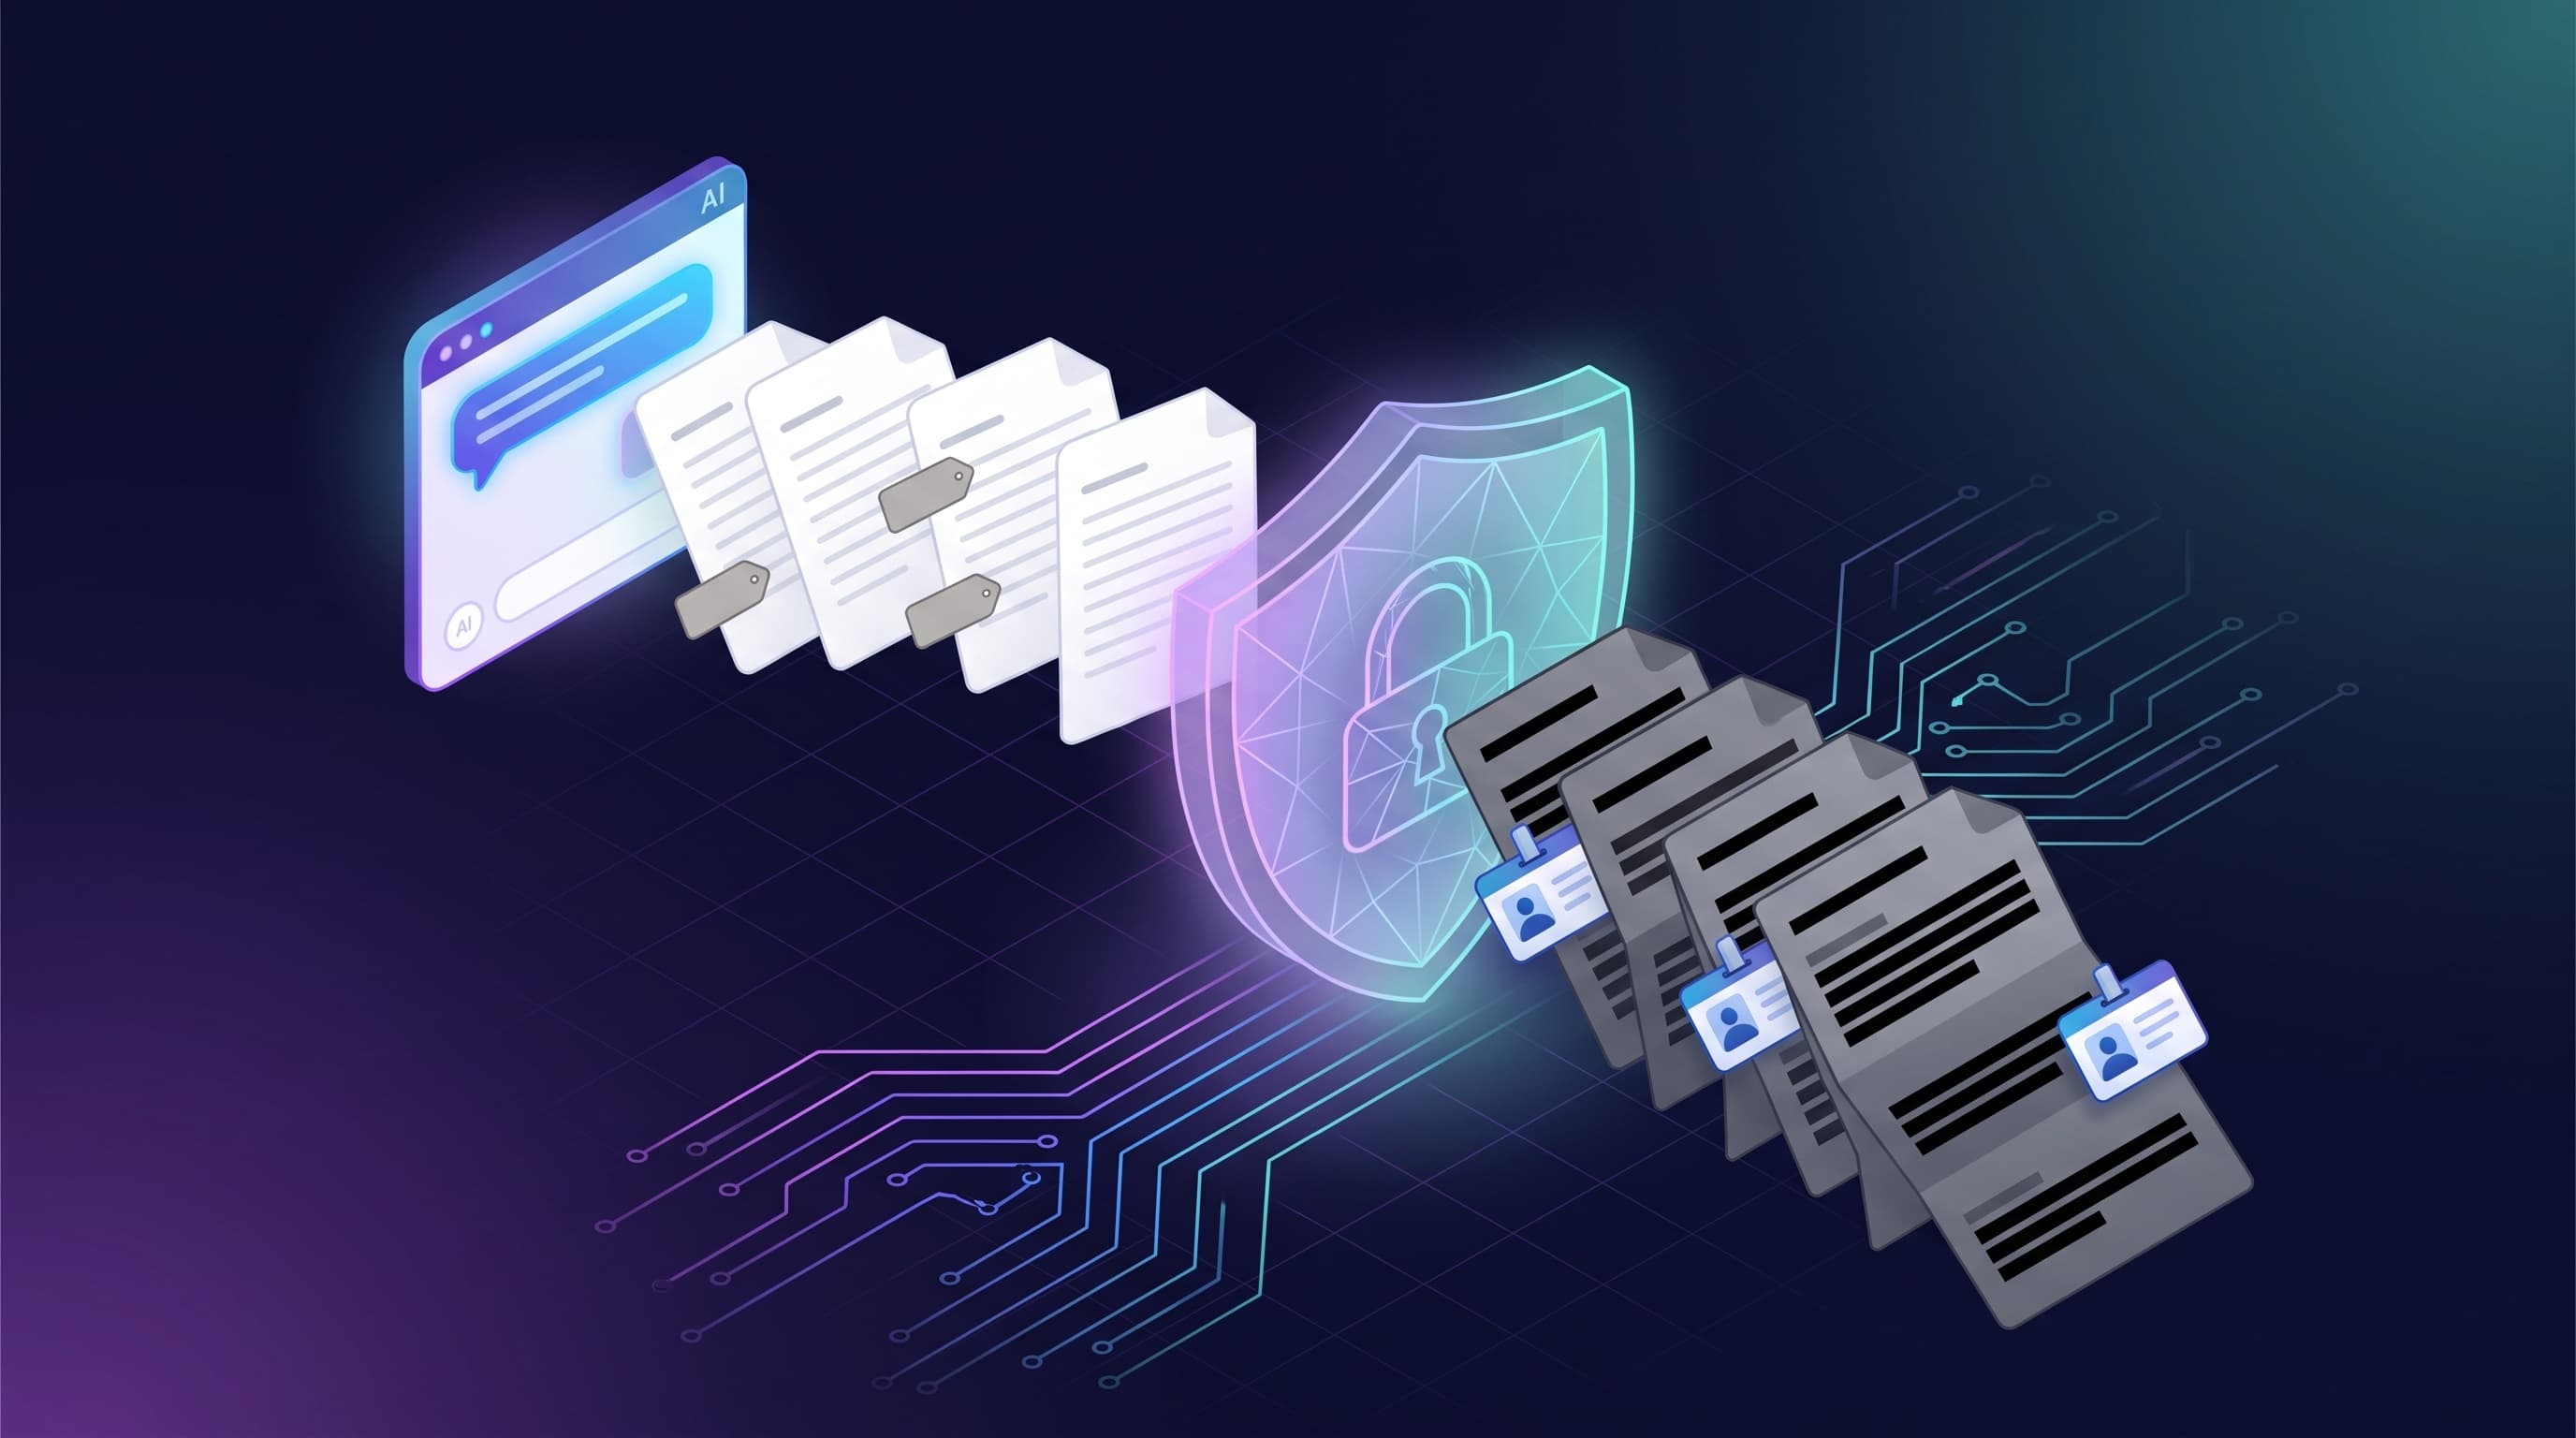
- Public AI tools under default settings may store what you enter and use it for training, and employees are feeding them far more than you realize
- According to LayerX, 77% of employees already paste data into GenAI tools, and 82% of those paste events happen from personal accounts, completely outside any organizational control
- The solution is not to block AI (that only drives usage underground), but an anonymization workflow: strip identifying details before uploading, work freely, then restore the details at the end
According to Cyberhaven, the share of sensitive data in everything employees feed into AI tools jumped from 10.7% to 34.8% in just two years. In other words, as AI use grows, employees are not getting more careful. They are getting less careful.
In nearly every organization in Israel, it's already happening: employees upload documents to AI tools to summarize, analyze, and draft. The question isn't whether it's occurring, but how much of it is happening without any oversight. According to Harmonic Security, sensitive information appears in 20% of the files employees upload to AI tools, and in most cases nobody in the organization knows about it.
This guide cuts through the noise: what actually happens to a document you upload to an AI tool, what the law requires, why manual workarounds collapse, and what a sound workflow looks like, one that gives your organization both the productivity gains and the peace of mind.
In short (TL;DR)
- Public AI tools under default settings may store what you enter and use it for training, and employees are feeding them far more than you realize
- According to LayerX, 77% of employees already paste data into GenAI tools, and 82% of those paste events happen from personal accounts, completely outside any organizational control
- The solution is not to block AI (that only drives usage underground), but an anonymization workflow: strip identifying details before uploading, work freely, then restore the details at the end
- Further in this guide: a complete five-step methodology, plus a free Israeli tool that handles this automatically in the browser, without the file ever leaving the computer
What actually happens to a document you upload to an AI tool?
The short answer: it depends on the tool and the settings, but in free-tier defaults, your content may be stored, used for model training, and accessible to vendor teams. For a sensitive organizational document, that is a problem.
To be precise: major vendors now offer business tiers (ChatGPT Team/Enterprise, Claude for Work, enterprise Copilot) that commit not to train on your data (law firms, for whom confidentiality is their lifeblood, will find the exact rules in the guide Claude for lawyers). But three issues remain open:
- Most actual usage doesn't happen there. According to LayerX, 82% of employees' paste events occur from personal accounts, not from the secured organizational account the organization paid for.
- Even without training, the data has left the organization. It has traveled to third-party servers, subject to breaches, legal orders, and policies that change.
- The document stays in the conversation history. A departing employee, a compromised account, or simply a phone left unlocked, and the history is there, with the document inside it.
The most widely reported case is Samsung in 2023: engineers pasted proprietary source code and an internal meeting transcript into ChatGPT, and the company blocked the tool entirely. That is exactly the reaction this guide is trying to spare you, because blocking doesn't work.
How much sensitive information is actually leaking into AI tools?
More than you think, and the trend is worsening. The numbers from the field:
| Data point | Source |
|---|---|
| Sensitive information found in 20% of files uploaded to AI tools and in 4% of prompts | Harmonic Security, 2025 |
| 34.8% of data employees enter into AI tools is sensitive, up from 10.7% in two years | Cyberhaven |
| 11% of what employees paste into ChatGPT is confidential: code, customer data, regulatory information | Cyberhaven Labs |
| 77% of employees paste data into GenAI tools; 82% from personal accounts | LayerX, 2025 |
The key takeaway: the problem is not malicious employees, it is productive ones. They found a tool that saves them hours, and nobody gave them a safe way to use it.
What does Israeli law say about this?
Amendment 13 to the Privacy Protection Law, which came into force in August 2025, changed the rules of the game: expanded enforcement powers for the Privacy Protection Authority and substantial financial penalties for organizations that transfer personal information to unauthorized parties. Uploading a document containing customer details to a public AI tool is precisely the type of incident the amendment targets.
In defense and classified organizations the bar is even higher: even a document at the BALMAS (unclassified) level is subject to information security procedures, and classified documents may not be uploaded to any external tool, full stop. There the question isn't "which tool" but "how do we prepare a version that can be worked on."
Why today's solutions break down
We see three patterns in organizations, and none of them hold up:
1. Full blocking. The organization blocks ChatGPT, and employees switch to their personal phones. The result: the exact same leakage, with zero organizational visibility. The LayerX figure of 82% usage from personal accounts is precisely this phenomenon.
2. Manual scrubbing. An employee sits down and replaces names by hand before pasting: "Moshe Cohen" becomes "Giraffe," "HaBarzel Street" becomes "HaPrachim Street." It works once. By the tenth time, someone misses an ID number buried in a table, forgets the file's metadata (author name, comments, tracked changes), or replaces inconsistently so the analysis comes out broken.
3. Policy without tooling. A policy document that says "do not enter sensitive information" without providing a practical way to work. An employee who needs to summarize a contract by tomorrow will work around the policy, not the deadline.
The real solution combines all three: a clear policy, plus a tool that makes the safe path the easy path.
How to do it right: the five-step anonymization methodology
Anonymization means replacing identifying details in a document with neutral substitutes, in a way that allows you to work on the content without exposing the people behind it. Done correctly, you get the full value from AI with zero exposure. Here is what a complete workflow looks like:
Step 1: Identification. Scan the document for all identifying details: names, national ID numbers (including check-digit validation), phone numbers, email addresses, street addresses, company and project names, amounts, bank account numbers. In defense organizations: also ranks, units, and personnel numbers.
Step 2: Metadata removal. The part everyone forgets: a Word file carries inside it the author's name, internal comments, and tracked changes that can expose more than the text itself.
Step 3: Consistent replacement. "Danny Cohen" becomes PERSON_001 in every occurrence throughout the document, not a different substitute each time. This is what preserves context: the AI still understands it is the same person throughout the document, and the analysis remains coherent.
Step 4: Human review. A person goes over the result before uploading: approves it, adds an item the system missed, or overrides a false positive. No automated detection is perfect, and the human eye is the last line of defense.
Step 5: Work and restore. Upload the clean version to whichever AI tool the organization approves, work freely, then at the end restore the real names into the output using the substitution map that only you have kept.
Which tool does this automatically?
The entire process can be done manually, but for daily use you need a tool. BALMAS AI (balmasai.com) is an Israeli tool built precisely around this methodology, and its security logic is appropriate even for sensitive organizations:
- The file never leaves the computer. Scanning and cleaning run in the browser itself, not on a server. The original document is not uploaded anywhere.
- Drag in a PDF, Word, Excel, PowerPoint, or CSV file and receive a risk score before and after.
- Detection tuned for Hebrew: national ID numbers with check-digit validation, Israeli phone numbers, names, companies, and amounts.
- Consistent replacement (the same person gets the same substitute across all 37 occurrences), full metadata removal, and a review screen where you decide on each item: keep, replace, or remove.
- Three cleaning levels (Standard / Strict / Maximum), so you can set a single organizational policy for everyone.
There is a free tier of 10 documents per month, no credit card required, open an account here. For anyone cleaning their first document: start at Strict, and drop to Standard only after you see what it catches.
What is BALMAS, and why is it relevant to your organization?
BALMAS is the Hebrew acronym for "unclassified," the baseline classification level in the Israeli defense system: information that is not secret but is still subject to handling rules. The concept is relevant to every organization: even your "ordinary" documents, contracts, meeting minutes, CVs, contain information that should not reach a third party. The difference between a defense organization and a business is a matter of degree, not of principle.
What does this mean for your organization? A two-minute check
Three questions worth asking this week:
- Do you have a written AI policy? Not a block, a policy: what is permitted, what is not, and which tools. If not, start with the guide to writing an AI policy for organizations.
- Do employees have a safe way to work with documents? If the only option is "don't do it," they are doing it on their personal phones.
- Who is responsible? In an organization with no owner for this topic, the answer to both previous questions will still be "no" a year from now.
Frequently asked questions
Does ChatGPT store what you enter? In the free version under default settings, conversations may be saved and used to improve the models; this can be turned off in settings. In business tiers (Team/Enterprise), the vendor commits not to train on your data. In any case, the data passes through the vendor's servers, which is why sensitive documents require anonymization before uploading.
What should not be entered into a public AI tool? As a rule of thumb: identifying details of customers and employees (names, national IDs, phone numbers), medical and financial information, code and confidential business information, and any classified or confidentiality-bound material. The content itself (the question, the structure, the analysis) is both permitted and desirable, once the identifying details have been replaced.
What is document anonymization? A process that replaces identifying details in a document (names, ID numbers, addresses, company names) with neutral and consistent substitutes, so that you can work on the content without exposing the people and entities behind it. Proper anonymization also includes metadata removal and maintains consistency: the same person receives the same substitute throughout the entire document.
Is it permitted to upload classified documents after anonymization? No. A classified document remains classified, and anonymization does not lower a classification, which is a formal authority belonging only to an authorized official. The tools and methodology in this guide are intended for sensitive but unclassified information (customer details, business information, BALMAS-level documents), and always subject to the organization's information security policy.
Doesn't anonymization hurt the quality of AI responses? When the replacement is consistent, almost not at all. The AI does not need to know that "PERSON_001" is Danny Cohen in order to summarize a contract or analyze a report. It needs to know that it is the same party throughout the document. That is why consistent replacement is the heart of the method, and random substitutes are what actually breaks the analysis.
The bottom line
AI is already inside your organization. The only question is whether it is there in a managed way. The formula that works: a written policy, a five-step anonymization process, and a tool that makes the safe path the easy path. An organization that gets this right gets both worlds: employees get the tools they want anyway, and the data stays home.
Want to go a step further, from policy through team-wide implementation? That is exactly what we cover in AI training workshops for organizations, including a safe-data-handling module in every session.
Want to understand in depth the tool that demonstrates this methodology in practice? The complete guide to Balmas AI walks through all five steps, the three cleaning levels, and Round-Trip Restore, one step at a time.
Frequently asked questions
Yaakov Tzedek
An Israeli AI lecturer, consultant and implementer who has supported 100+ organizations in AI implementation and lectured for 200+. Official content partner of Meta, Google, Canva and TikTok, featured on Israel's Channel 13.
More about Yaakov →